
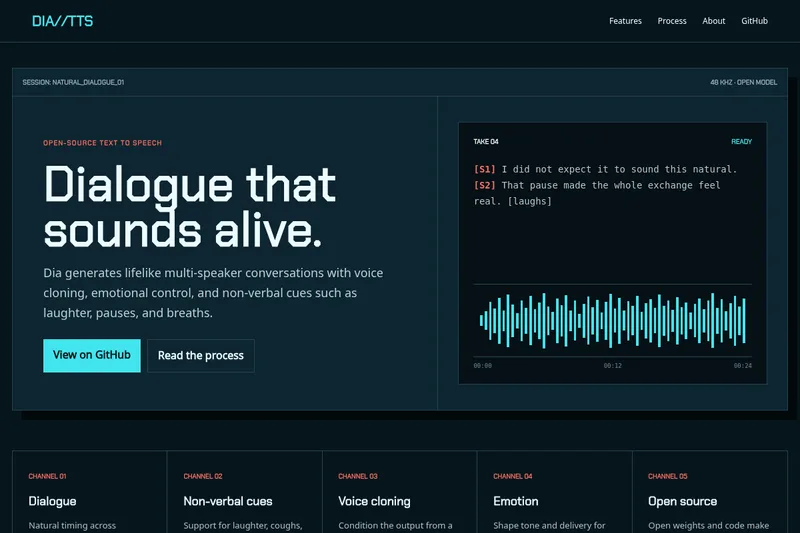
Diatts
Dia TTS is an open-source, Apache-2.0 text-to-speech model designed for realistic multi-speaker dialogues with voice cloning, emotional control, and non-verbal sound generation.
Diatts is voice & speech software teams evaluate for content & marketing. Use this page to review pricing, integration signals, and the best alternatives before you commit.
Profile facts come from the vendor source. AiMatch labels unknown pricing or API details instead of estimating them.
Review official source →Quick Overview
Best for: Content & Marketing
What it does
Voice & Speech software for decision-makers comparing workflow fit and alternatives.
Best fit
Content & Marketing
Pricing snapshot
Freemium from Free
Next step
Compare Diatts with similar tools before you shortlist it.
Compare this tool before you shortlist it
Review alternatives, pricing posture, and workflow fit side by side.
Dia TTS is an open-source text-to-speech model (Apache 2.0) focused on producing natural multi-speaker dialogues. It supports voice cloning from short audio samples, fine-grained emotion and tone control, and the generation of non-verbal sounds such as laughter and coughs. The model is presented as usable via a web demo and downloadable/open weights, and is optimized for real-time performance on consumer-grade GPUs, targeting content creators, developers, educators, and enterprise integrations.
Dia TTS is an open-source, Apache-2.0 text-to-speech model designed for realistic multi-speaker dialogues with voice cloning, emotional control, and non-verbal sound generation.
Own this listing?
Claim this page for a one-time $29 to add pricing, features, screenshots, verified owner details, and a clearly labeled 30-day category position after the profile is live.
Claim this listing for $29Key Features
Realistic Dialogue Generation
Generates lifelike multi-speaker conversations with natural timing, pauses, interruptions, and variations in speaking speed.
Non-Verbal Sound Support
Can produce non-verbal sounds (e.g., laughter, coughing, throat clearing) directly from text cues, removing the need for separate sound effects.
Voice Cloning
Mimics any voice using a short audio sample to produce personalized output and consistent voices across projects.
Emotion and Tone Control
Allows adjustments to speech emotion and tone for expressive, context-appropriate output; supports SSML tags and emotion parameters.
Open Source (Apache 2.0)
Weights and code are openly available under the Apache 2.0 license for free use, modification, and research.
Large Model & Transformer Architecture
Uses a 1.6 billion parameter transformer-based model to capture intonation, rhythm, and long-context coherence.
Audio Conditioning
Supports reference audio conditioning to guide voice style and emotion for more precise outputs.
Real-Time Optimizations
Optimized for fast generation on consumer-grade GPUs to enable near real-time use cases.
Pricing
Free tier available for testing and development; free tier limit of up to 1000 characters per request.
Free
Free- Free tier for testing and development
- Character limit: up to 1000 characters per request (free tier)
Paid (Usage-based)
Usage-based paid plans (no specific prices listed)- Higher per-request character limits than free tier
- Scalable usage-based billing
Enterprise
Custom pricing- Customizable enterprise plans and higher limits
- Priority support and custom integration assistance for enterprise customers
Use Cases
Content Creation
Generate dialogue for podcasts, audiobooks, and videos with multiple speakers and embedded non-verbal sounds.
Language Learning
Create realistic conversations for listening and speaking practice with controllable tone and emotion.
Customer Support
Power virtual assistants with more human-like interactions to improve automated support experiences.
Game Development
Produce lifelike character voices and interactions useful for indie developers and rapid prototyping.
Advertising & Marketing
Generate emotionally controlled voiceovers for ads and marketing materials to support fast iteration and A/B testing.
Integrations
REST API
Provides a robust REST API for developers to integrate Dia TTS into applications (site states API is available and well-documented).
Open Weights & GitHub
Code and model weights are available publicly (open-source) for integration, research, and customization via GitHub.
Benefits
Limitations
No verified limitations are available.
Frequently Asked Questions
What is DIA-TTS?
How accurate is the voice cloning feature?
What languages are supported?
Is there an API available?
What are the pricing options?
How can I control emotions in the generated speech?
What file formats are supported?
Is there a character limit per conversion?
What kind of support do you offer?
How secure is the service?
Getting Started
- 1 Step 1: Input your script into the interface, using speaker tags like [S1], [S2] and non-verbal cues such as (laughs).
- 2 Step 2: (Optional) Upload a reference audio file to guide voice style or enable voice cloning.
- 3 Step 3: Click 'Generate' to produce speech from the provided text and parameters.
- 4 Step 4: Preview the generated audio in the interface and download the file if satisfied.
Support
docs
Detailed documentation, API references, and code examples are provided (site states documentation is available).
Contact via listed email address: [email protected]
customer service
Dedicated customer service and priority enterprise support are offered for paid/enterprise customers.
API
Robust REST API that is well-documented and supports various programming languages and frameworks (no direct documentation URL provided on the supplied page).
Rate limits vary by plan; free tier limit is up to 1000 characters per request.
Compare Diatts with similar tools
See how it stacks up against alternatives
Related Tools
View all 98 →
Join the Mic Captions beta
Mic Captions (beta) is a TestFlight beta app that turns spoken audio into real-time, easy-to-read captions on iPhone and iPad, with translation, session saving, transcript replay, and navigation by Topics and Words.
FLOW Speak
FLOW Speak offers browser-based English speaking practice with short lessons, structured CEFR learning pathways, and AI-powered feedback. Its Pathways take learners from A2 to B1, B1 to B2, or B2 to C1 through staged lesson levels.
steosvoice
SteosVoice (formerly CyberVoice) provides high-quality neural voice AI and speech synthesis for creators and businesses, enabling dubbing, voiceovers, audiobooks, game/mod voices, Telegram bot text-to-speech, and voice licensing to monetize voice assets.
AudioPod AI
AudioPod AI is a browser-based AI audio workstation for creating audiobooks, podcasts, music, and voiceovers with features like multi‑speaker podcast generation, voice cloning and 200+ languages, transcription, stem splitting, noise reduction, and a unified audio API.
ttsMP3.com
ttsMP3.com is a free web-based text-to-speech service that converts text (US English and 28+ languages) into downloadable MP3 audio using a variety of natural-sounding voices (including AI voices) and supports SSML-style tags for prosody and effects.
whisperbot
WhisperBot is an AI-powered WhatsApp assistant that transcribes forwarded voice messages into text and can provide key takeaways from long messages. It supports more than 57 languages and works inside WhatsApp without requiring another app.
Vibevoice
VibeVoice AI is an open-source Microsoft Research framework for long-form, multi-speaker text-to-speech that can generate up to 45–90 minutes of continuous, context-aware audio with support for up to four distinct speakers and English/Chinese outputs, distributed under an MIT license with pretrained weights on GitHub and Hugging Face.
Premium Alternatives
Bswan
Bswan is a managed conversion infrastructure platform that uses AI voice and messaging funnels to activate new users, recover early churn, and increase lifetime value by running telephony, messaging, routing, tracking and continuous optimization for campaigns at scale.

SigmaMind AI (sigma-ai)
SigmaMind AI (sigma-ai) is a voice AI platform that creates deployable voice agents for call centers to handle outbound and inbound campaigns—lead generation, debt collection, appointment setting, and customer support—integrating with existing dialers and CCaaS stacks.