Voice AI that runs on CPUs
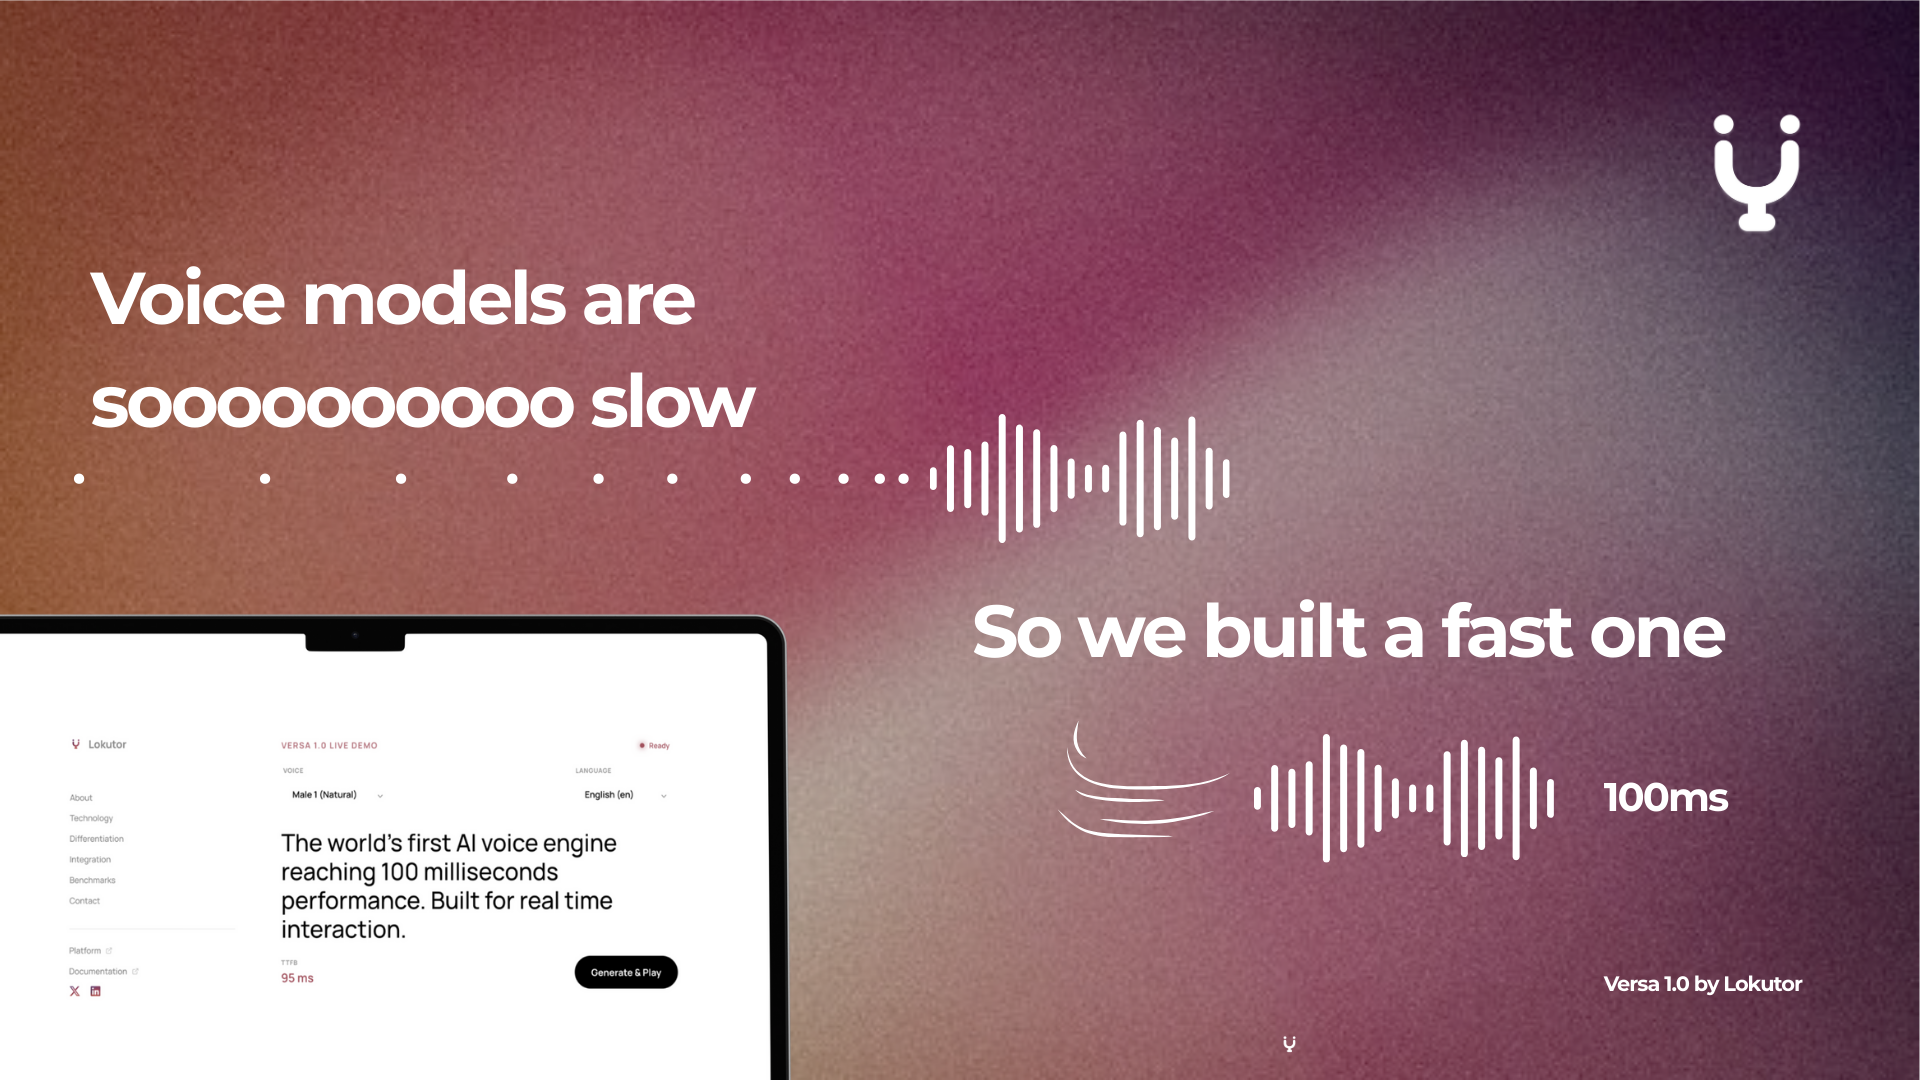
Lokutor provides CPU-native voice agents and a full voice pipeline — speech-to-text, turn-taking, noise suppression and text-to-speech — that run without GPUs in cloud, on-premises, or on-device environments for multilingual voice applications.
Voice AI that runs on CPUs is voice & speech software teams evaluate for voice & speech. Use this page to review pricing, integration signals, and the best alternatives before you commit.
Profile facts come from the vendor source. AiMatch labels unknown pricing or API details instead of estimating them.
Review official source →Used in These Packs
Quick Overview
Best for: Voice & Speech
What it does
Voice & Speech software for decision-makers comparing workflow fit and alternatives.
Best fit
Voice & Speech
Pricing snapshot
Free from Free (no card)
Next step
Compare Voice AI that runs on CPUs with similar tools before you shortlist it.
Compare this tool before you shortlist it
Review alternatives, pricing posture, and workflow fit side by side.
Lokutor provides a CPU-native voice AI pipeline that includes noise suppression (Psst), turn-taking (Turno), speech-to-text, orchestration and speech synthesis — explicitly designed to run without GPUs. The product is offered to run in three deployment modes: on Lokutor's cloud (quick start, per-minute plans and a free plan), inside a customer's perimeter (on ARM64 & x86, auditable for regulated teams), or directly on devices (offline, no round-trip). The site emphasizes multilingual support, multiple voices, and low latency on ordinary CPU instances.
Turn-taking, noise suppression and speech synthesis built for commodity CPUs. No GPUs. Deploy in your cloud, on-prem, or on the device.
Own this listing?
Claim this page for a one-time $29 to add pricing, features, screenshots, verified owner details, and a clearly labeled 30-day category position after the profile is live.
Claim this listing for $29Key Features
CPU-native pipeline (no GPU)
The entire voice pipeline is designed to run on ordinary processors — no GPUs anywhere in the pipeline.
Five-stage pipeline
A five-stage pipeline where four stages are Lokutor's own CPU models (noise suppression, turn-taking, speech-to-text, orchestration and synthesis).
Turn-taking (Turno)
Turno decides whose turn it is by what it hears (true interruptions pass the turn rather than relying on silence timers).
Noise suppression (Psst)
Noise suppression that isolates the speaker's voice from room noise (demonstrated as 'Psst' on the site).
Speech-to-text and speech synthesis
Streaming speech-to-text and text-to-speech capabilities integrated in the CPU pipeline.
Multilingual and multi-voice support
Support for 33 languages and 10 voices (visemes included); users can pick language and voice on the demo interface.
Low-latency streaming
Latency guidance shown on the site (≈120 ms first audio in streaming mode; ≈0.9 s to first reply, ≈1.3 s with turn detection on a 4‑vCPU node).
Deploy anywhere
Runs on Lokutor's cloud, inside customer servers (ARM64 & x86) or directly on the device for offline operation.
Pricing
Free plan available with no credit card required.
Free
Free (no card)- Access to a free plan on Lokutor's cloud
- Quick evaluation and demo access
Per-minute cloud plans
Per-minute pricing (details on site)- Plans include synthesis, transcription and orchestration
- EU-hosted options available
Use Cases
Customer training and onboarding
Create guided onboarding and training voice modules (the site shows examples for onboarding walkthroughs and training syllabi).
Customer support & call automation
Deploy empathetic or instructive voice agents for support workflows and sales interactions.
On-device voice agents and robotics
Run the full pipeline on-device for offline agents and robotics with no round-trip and no lifetime inference bill.
Regulated or privacy-sensitive deployments
Run the pipeline inside your perimeter so audio never leaves and solutions can be auditable for regulated teams.
Integrations
LLM providers
The pipeline integrates with a language model provider ('Your provider' referenced) for conversational responses.
Orchestrator (GitHub)
An Orchestrator is available on GitHub (link referenced on the site) for developer integration.
Pipecat integration
Pipecat integration is listed in the site footer as an available integration.
Benefits
Limitations
Frequently Asked Questions
No verified FAQs are available.
Getting Started
- 1 Step 1: Visit the site and Start building or Book a demo to evaluate the product.
- 2 Step 2: Sign in or create an account to access the cloud dashboard (free plan available, no card).
- 3 Step 3: Pick a voice and language in the dashboard or try the demo (press the mic or upload a WAV) and then choose deployment: Lokutor cloud, your servers, or on-device.
Support
Contact: [email protected] (listed on the site footer).
docs
Developers Documentation is available via the site.
sales/demo
Book a demo through the site to discuss running Lokutor inside your environment.
API
Developers Documentation and an Orchestrator repository on GitHub are referenced on the site for developer integration.
Compare Voice AI that runs on CPUs with similar tools
See how it stacks up against alternatives
Related Tools
View all 88 →
Join the Mic Captions beta
Mic Captions (beta) is a TestFlight beta app that turns spoken audio into real-time, easy-to-read captions on iPhone and iPad, with translation, session saving, transcript replay, and navigation by Topics and Words.
Call-an-AI
Call-an-AI provides phone-callable conversational AI bots (24/7) for personal and business use — pay-as-you-go voice AI at 15¢/minute with calls under 4 minutes free, plus options to customize and build your own bot.
Aivoicecloning
AI Voice Cloning is a web-based service that creates high-quality, multilingual AI voice clones in seconds from short audio samples, offering text-to-speech generation, voice style customization, and downloadable audio for content, marketing, and corporate use.


Aivoicelab
AI Voice Lab provides an AI voice generator that converts text to natural-sounding speech for videos, podcasts, audiobooks, IVR and other content, offering a large library of character and language voices plus upload/recording and fine-grain voice controls.
Vibevoice
VibeVoice AI is an open-source Microsoft Research framework for long-form, multi-speaker text-to-speech that can generate up to 45–90 minutes of continuous, context-aware audio with support for up to four distinct speakers and English/Chinese outputs, distributed under an MIT license with pretrained weights on GitHub and Hugging Face.
AudioPod AI
AudioPod AI is a browser-based AI audio workstation for creating audiobooks, podcasts, music, and voiceovers with features like multi‑speaker podcast generation, voice cloning and 200+ languages, transcription, stem splitting, noise reduction, and a unified audio API.
Premium Alternatives
Bswan
Bswan is a managed conversion infrastructure platform that uses AI voice and messaging funnels to activate new users, recover early churn, and increase lifetime value by running telephony, messaging, routing, tracking and continuous optimization for campaigns at scale.

SigmaMind AI (sigma-ai)
SigmaMind AI (sigma-ai) is a voice AI platform that creates deployable voice agents for call centers to handle outbound and inbound campaigns—lead generation, debt collection, appointment setting, and customer support—integrating with existing dialers and CCaaS stacks.

TalkForce AI
TalkForce AI provides AI-powered voice/call agents that automate customer service conversations—handling routine inquiries, bookings, cancellations, and outbound calls—while integrating with existing systems and handing off to humans when needed.