Awan LLM
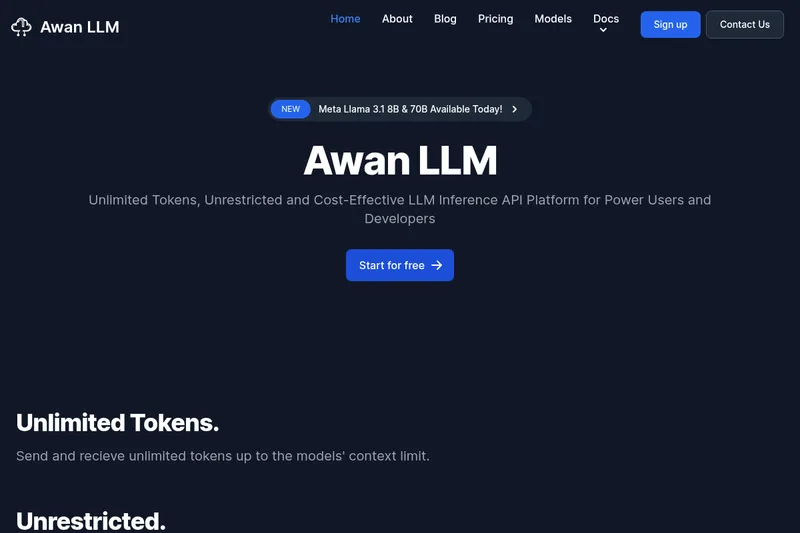
Awan LLM offers developers and power users an LLM inference API with monthly pricing and unlimited token generation up to each model’s context limit. Users send requests to API endpoints to support applications, agents, data processing, and code completion.
One of 672 tools in AI Agents
Who it's for
- Developers building AI-powered applications who want to use Awan LLM API endpoints with monthly rather than per-token pricing.
- Teams processing large amounts of data with LLMs, within model context and request rate limits.
- Developers using LLMs for code completion or AI agents who want to avoid per-token billing.
Not the right fit if…
- Teams whose requests must exceed a model’s context limit: generation is subject to each model’s context limit.
How it fits your workflow
Sign up for an account and consult the Quick-Start page to learn how to use Awan LLM API endpoints. Send requests to an available model and use the generated output in applications or workflows such as assistants, agents, data processing, and code completion.
Awan LLM says it runs its own datacenters and GPUs. Token generation is advertised as unlimited up to model context limits, while request rate limits still apply.
Pricing
Free: Start for free
Free / Trial
Start for free
- · Access to the platform to begin using models (details on site)
Paid (Monthly)
Monthly subscription (price details not listed on the provided content)
- · Unlimited tokens up to model context limit
- · Pay per month instead of per token
Prices checked on Jul 16, 2026 from the vendor's site. They can change; confirm before you buy.
Key features
- Unlimited Tokens
- Send and receive unlimited tokens up to the models' context limit.
- Unrestricted Outputs
- Use LLM models without constraints or censorship.
- Cost-Effective Monthly Billing
- Pay per month instead of paying per token, reducing per-token billing concerns.
- Hosted Models
- Provides hosted models such as Meta Llama 3.1 (8B & 70B).
- API Endpoints & Quick-Start
- API endpoints with a Quick-Start guide for developers to begin integration after signup.
- Privacy — No Logging
- The site states that prompts and generations are not logged, per the Privacy Policy.
Works with
- Meta Llama 3.1 (8B & 70B)
Limitations to know
- Generation is subject to each model’s context limit.
- Request rate limits apply; the supplied content does not state their numerical values.
Alternatives to consider
-
Featherless
Choose it if you want a serverless platform for tens of thousands of open-source models, with predictable flat-rate pricing and dedicated GPU options.
-
LiteLLM
Choose it if you need a self-hosted gateway to route requests across many model providers with observability, guardrails, and budgeting features.
-
Aimlapi
Choose it if you need a unified API gateway offering access to 1000+ AI models across chat, image, video, audio, and embeddings.
Getting started
- Sign up for an Awan LLM account.
- Consult the Quick-Start page for API endpoint instructions.
- Choose an available model and use its API endpoint, accounting for context and request rate limits.
Frequently asked questions
How can you provide unlimited token generation?
Unlike other API providers, we own our own datacenters and GPUs.
How do I use this?
Sign up for an account and then check out our Quick-Start page to see how easy it is to use our API endpoints.
How do I contact Awan LLM support?
You can contact us at [email protected] or click the contact button at the top of the page.
Do you keep logs of prompts and generation?
No. We do not log any prompt or generation as explained in our Privacy Policy page.
Why is Awan LLM better than other LLM API providers?
They provide unlimited token generations making it cheaper than other providers that charge based on tokens sent and received.
Is there a hidden limit imposed?
We only have request rate limits which are clearly explained in our Models and Pricing page.
Why use Awan LLM API instead of self-hosting LLMs?
It will cost you significantly less to use our API than renting GPUs in the cloud or paying electricity to run your own GPUs.
What if I want to use a model that's not here?
If a model you want to use is not in our Models page, you can contact us to request to add it.