The cheapest GPU cloud
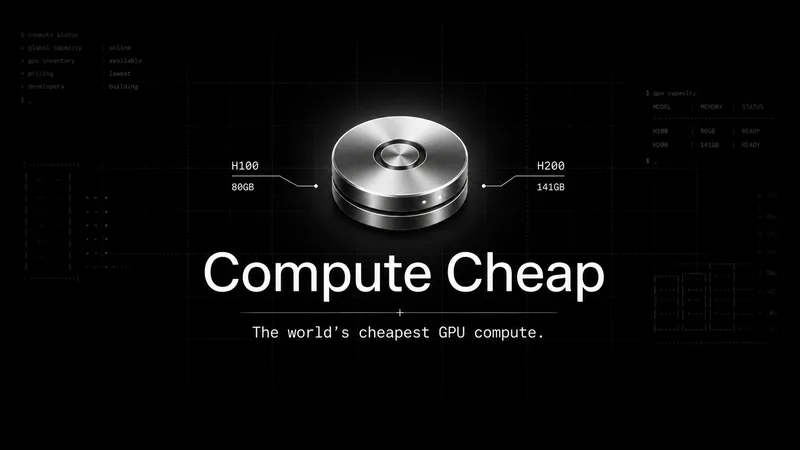
Compute Cheap provides low-cost GPU compute for training and inference, offering H100 and H200 SXM GPUs as interruptible or reserved capacity with published per-GPU-hour pricing and a simple request/reserve/run workflow.
The cheapest GPU cloud is ai agents software teams evaluate for ai agents. Use this page to review pricing, integration signals, and the best alternatives before you commit.
Profile facts come from the vendor source. AiMatch labels unknown pricing or API details instead of estimating them.
Review official source →Quick Overview
Best for: AI Agents
What it does
AI Agents software for decision-makers comparing workflow fit and alternatives.
Best fit
AI Agents
Pricing snapshot
Freemium from $1.15 per GPU-hour (updated Sep 4, 2026)
Next step
Compare The cheapest GPU cloud with similar tools before you shortlist it.
Compare this tool before you shortlist it
Review alternatives, pricing posture, and workflow fit side by side.
Compute Cheap positions itself as a provider of very low-cost GPU compute for training and inference, explicitly offering NVIDIA H100 SXM 80GB and H200 SXM 141GB capacity. It publishes per-GPU-hour prices for interruptible and reserved capacity (for example, H100 interruptible listed at $1.15 per GPU-hour, updated Sep 4, 2026) and advertises being "the world's cheapest GPU compute." The product targets teams running frontier models by providing limited reserved and interruptible capacity in launch sizes from 1 to 8 GPUs, with a minimum reservation of 2,000 GPU-hours and a three-step flow: request capacity, confirm availability with a 50% upfront prepayment, then run workloads.
Affordable H100 and H200 GPU compute for training, inference, and everything in between.
Own this listing?
Claim this page for a one-time $29 to add pricing, features, screenshots, verified owner details, and a clearly labeled 30-day category position after the profile is live.
Claim this listing for $29Key Features
H100 & H200 GPU options
Offers H100 SXM 80GB and H200 SXM 141GB GPUs for training and inference, listed as available in launch sizes from 1 to 8 GPUs.
Interruptible and Reserved capacity
Two capacity types: interruptible (lower cost, can be reclaimed) and reserved (fixed rate for the full block).
Published per-GPU-hour pricing
Shows explicit hourly rates such as H100 interruptible $1.15/hr, H100 reserved $1.19/hr, H200 interruptible $1.39/hr, and H200 reserved $1.99/hr.
Block reservation workflow
Three-step process: request capacity, confirm availability and prepay 50% to reserve the block, then run workloads against the reserved GPUs.
Minimum reservation
Minimum reservation is 2,000 GPU-hours per request.
Market benchmarking chart
Interactive chart to compare the provider's price against daily market benchmarks across a 31-day window.
Pricing
H100 Interruptible
$1.15 per GPU-hour (updated Sep 4, 2026)- Lower-cost but interruptible (can be reclaimed)
- Launch sizes 1–8 GPUs
H100 Reserved
$1.19 per GPU-hour- Fixed rate for the reserved block
- Minimum reservation 2,000 GPU-hours
H200 Interruptible
$1.39 per GPU-hour- Lower-cost but interruptible
H200 Reserved
$1.99 per GPU-hour- Fixed reserved rate
Use Cases
Training frontier models
Provision H100/H200 capacity for multi-GPU training runs; the product emphasizes usage by teams training frontier models.
Inference and serving
Run inference and serving workloads on H100/H200 GPUs as part of production or research pipelines.
Fault-tolerant or batch training
Use interruptible capacity for cheaper batch or fault-tolerant training jobs that can tolerate preemption.
Integrations
No verified integration details are available.
Benefits
Limitations
Frequently Asked Questions
What's the difference between reserved and interruptible capacity?
Is there a minimum reservation?
How does the 50% deposit work?
What happens if the capacity I asked for isn't available?
Which GPUs can I request?
How is the price calculated?
Getting Started
- 1 Step 1: Request capacity — choose H100 or H200, select interruptible or reserved, and specify GPU-hours (minimum 2,000 GPU-hours).
- 2 Step 2: Confirm availability — Compute Cheap confirms availability for your exact request and you prepay 50% upfront to reserve the block.
- 3 Step 3: Run your workload — use the reserved GPUs to train, serve, and scale; remaining 50% is billed as usage completes.
Support
Contact support via [email protected] (address shown in site footer).
contact page
Site includes a 'Contact' link in the header for additional inquiries.
docs / blog
Blog and pricing posts linked on the site provide pricing history and infrastructure explanations.
API
Compare The cheapest GPU cloud with similar tools
See how it stacks up against alternatives
Related Tools
View all 651 →
Needle2
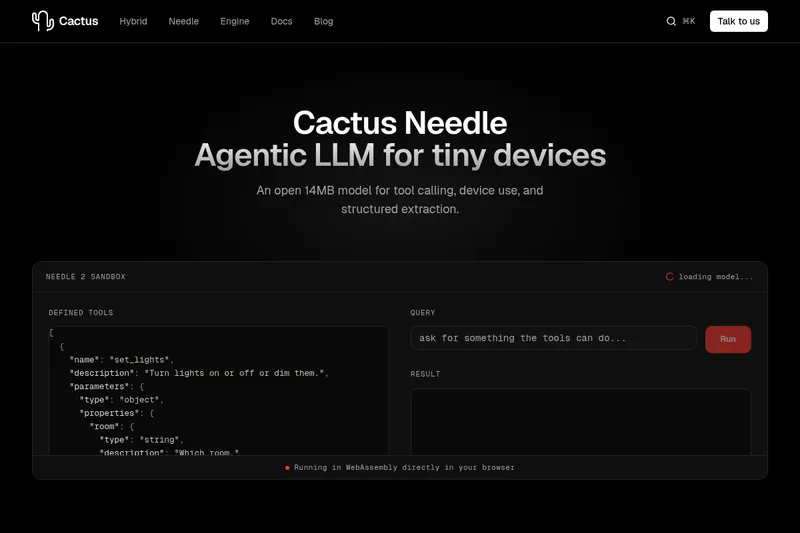
Needle 2 is an open, production-ready 45M-parameter agentic LLM from Cactus designed for tool calling, device control, and structured extraction on extremely small devices; the shipped CQ2-bit binary is ~14 MB and runs in ~28 MB of RAM across Cortex-M, microcontrollers, phones, Raspberry Pi and WebAssembly.
Oodle.ai
Oodle Agent Observability provides agent/LLM observability at scale with S3-backed columnar storage, fast search (<1s P99), out-of-the-box AI-powered insights, and flat ingestion-based pricing designed to retain 100% of traces affordably for debugging and optimizing production agents.


AgentDrive
AgentDrive is a cloud filesystem by Token Canopy that provides durable, shared drives for AI agents and human teammates to store and share files and context across work sessions, with an API intended for direct agent use.
Premium Alternatives
Abliterated LLM provider for cyber tasks
Refuseless hosts GLM 5.3 Abliterated models through an OpenAI-compatible API for cybersecurity and coding work. The page states that prompts are not retained and shows integrations with OpenCode and Pi.
PHNTM ONE
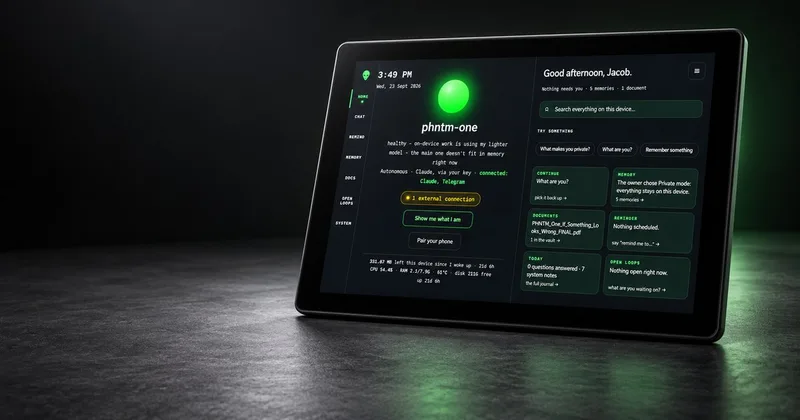
PHNTM One is a private, local-first AI appliance: a hand-built desktop device (Raspberry Pi 5, 8 GB, 10.1″ touchscreen) that runs an on-device model (Gemma 3 4B) to provide a voice-capable assistant, memories, document reading, timers, Home Assistant integration and offline knowledge — sold as a one-time $549 purchase with no subscription and zero telemetry by default.
AletheionAGI
AletheionAGI provides a grounded-memory layer for AI systems that enforces evidence-bound delivery, namespace isolation, and policy authorization so AI readers cannot produce unsupported claims. It's targeted at production-facing use cases like customer support, commerce agents and internal copilots.
ClaudeThings
ClaudeThings provides a packaged, continuously-updating set of 89 specialized agents, 103 pre-built skills, and 181 slash commands that act as an AI engineering and marketing team for Claude Code — delivered as a private GitHub repo and installed with a single npx command. It adapts to any stack via a CLAUDE.md project manifest and is sold as a one-time purchase with lifetime updates.

Keybe AI (Keybe INC)
Keybe AI (Keybe INC) is an AI-powered sales suite that provides deployable 'AI salesperson' assistants and a Smart Chat sales platform (CDP, funnels, outbound, catalogs, metrics and flows) for businesses to automate customer service and increase conversions.
