cerebrium
Cerebrium is a serverless, real-time AI infrastructure platform for deploying and scaling AI workloads — including LLMs, voice agents, video models, and multimodal pipelines — with fast cold starts, instant autoscaling, and multi-region GPU access for teams and production applications.
cerebrium is ai agents software teams evaluate for ai agents. Use this page to review pricing, integration signals, and the best alternatives before you commit.
Profile facts come from the vendor source. AiMatch labels unknown pricing or API details instead of estimating them.
Review official source →Used in These Packs
Quick Overview
Best for: AI Agents
What it does
AI Agents software for decision-makers comparing workflow fit and alternatives.
Best fit
AI Agents
Pricing snapshot
Contact for pricing
Next step
Compare cerebrium with similar tools before you shortlist it.
Compare this tool before you shortlist it
Review alternatives, pricing posture, and workflow fit side by side.
Cerebrium provides serverless GPU infrastructure optimized for real-time AI workloads, enabling teams to deploy voice agents, video models, large language models, and other AI applications with low-latency cold starts and automatic autoscaling. The platform emphasizes production readiness: fast container startup using memory and GPU snapshotting, autoscaling across thousands of GPUs without reservations or lock-ins, and multi-region deployments to meet data residency requirements. Cerebrium targets teams and organizations that need reliable, observable, and secure infrastructure for production-grade AI.
Serverless AI infrastructure platform for building, deploying, and scaling AI applications with cost savings.
Own this listing?
Claim this page for a one-time $29 to add pricing, features, screenshots, verified owner details, and a clearly labeled 30-day category position after the profile is live.
Claim this listing for $29Key Features
Fast cold starts (snapshots)
Memory and GPU snapshotting to launch containers in seconds and reduce cold-start latencies.
Instant autoscaling
Automatic, real-time scaling of workloads to handle bursts and scale-outs without manual capacity planning.
Multi-cloud, multi-region GPU access
Instant access to thousands of GPUs across multiple clouds and regions with no reservations or lock-ins.
Bring-your-own-code
Run user code or Dockerfiles unchanged — point to an entry point or Dockerfile and Cerebrium runs it versioned and reproducibly.
Observability
End-to-end observability with logs, metrics, scaling events, system performance, and native OpenTelemetry support.
Security & Compliance
Security foundations including SOC 2, HIPAA, GDPR, ISO compliance, gVisor-based workload isolation, and data residency controls.
Multiple endpoint types
Support for WebSocket endpoints, streaming endpoints, and REST API endpoints for serving models and real-time agents.
Deployment tooling
Support for custom Dockerfiles, CI/CD workflows, secrets management, concurrency & batching, asynchronous jobs, and distributed storage.
12+ GPU types
Support for a variety of GPU hardware types to match workload requirements.
Pricing
Current pricing details are not available from the vendor source.
Use Cases
Low-latency voice agents
Deploy voice agents that respond with low latency (examples show 500ms voice agents and Twilio/LiveKit integrations).
Transcription at scale
Transcribe long-form audio quickly (example: transcribe a 1 hour podcast in under 2 minutes).
Serving open-source LLMs
Deploy and serve open-source models with vLLM or other inference backends.
Video and image models
Run generative and VLM workloads such as Stable Diffusion XL and other image/video models.
High-throughput embeddings & reranking
Provide a low-latency, high-throughput REST API for embeddings and reranking models.
Inference performance tuning
Deploy Triton Inference Server with TensorRT-LLM for high-throughput inference and specialized optimizations.
Model training and hyperparameter sweeps
Run training jobs and hyperparameter sweeps (example: Llama 3.2 with WandB).
Model-backed web apps
Deploy chat interfaces and web UIs using FastAPI + Gradio or similar frameworks.
Ad analysis and multimodal pipelines
Deploy VLMs and pipelines (example: building intelligent ad analysis systems with SGLang).
Integrations
OpenTelemetry
Native OpenTelemetry support to connect Cerebrium observability to existing monitoring stacks.
Twilio
Example integration for building voice agents that handle telephony interactions.
LiveKit
Used in examples to build outbound calling agents and real-time audio workflows.
WandB
Example integration for running hyperparameter sweeps and tracking training experiments.
Gradio / FastAPI
Examples show deploying interactive chat interfaces using FastAPI and Gradio on Cerebrium.
Triton + TensorRT-LLM
Example deployment path for achieving high-throughput inference with Triton and TensorRT-LLM.
vLLM
Support for serving open-source LLMs using vLLM as an inference backend.
Stable Diffusion XL
Examples demonstrating image generation workflows using SDXL and refiners.
Benefits
Limitations
No verified limitations are available.
Frequently Asked Questions
No verified FAQs are available.
Getting Started
- 1 Step 1: Visit the site and sign up or click 'Try it now' / 'Book a demo' to start an evaluation.
- 2 Step 2: Point Cerebrium to your application entry point or provide a Dockerfile (bring-your-own-code).
- 3 Step 3: Launch runs via the CLI (example shown: 'cerebrium run ...') or dashboard, then monitor logs, metrics, and scaling events through the observability stack.
Support
docs
Documentation and tutorials are linked from the site (Docs link present in site navigation).
status
Status page referenced on the site for uptime and incident information.
contact / sales
Contact Us and Book a demo links for sales and pre-sales support.
blog
Product updates, tutorials, and case studies available via the site's blog.
API
Compare cerebrium with similar tools
See how it stacks up against alternatives
Related Tools
View all 651 →
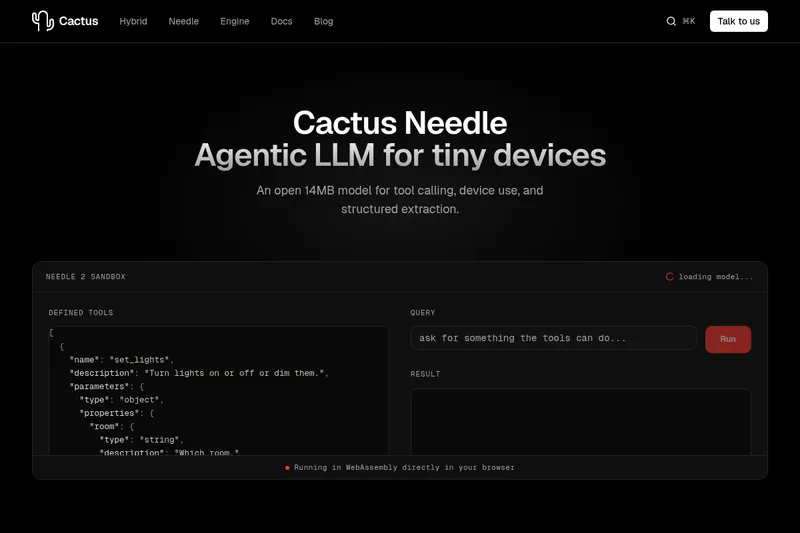
Needle2
Needle 2 is an open, production-ready 45M-parameter agentic LLM from Cactus designed for tool calling, device control, and structured extraction on extremely small devices; the shipped CQ2-bit binary is ~14 MB and runs in ~28 MB of RAM across Cortex-M, microcontrollers, phones, Raspberry Pi and WebAssembly.
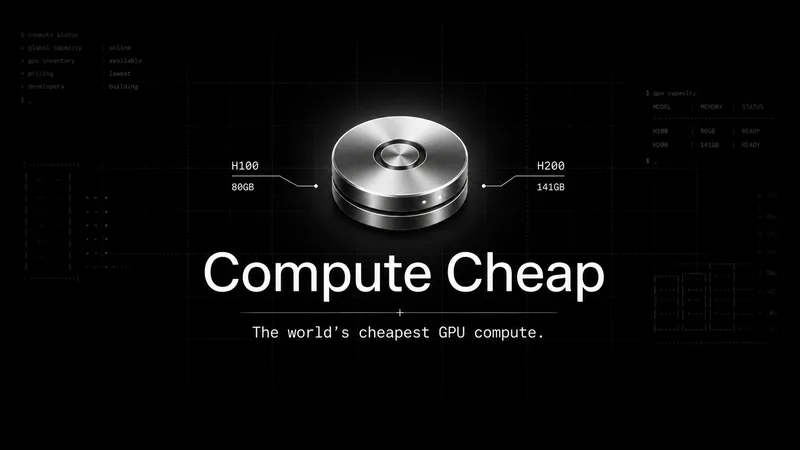
The cheapest GPU cloud
Compute Cheap provides low-cost GPU compute for training and inference, offering H100 and H200 SXM GPUs as interruptible or reserved capacity with published per-GPU-hour pricing and a simple request/reserve/run workflow.
Oodle.ai
Oodle Agent Observability provides agent/LLM observability at scale with S3-backed columnar storage, fast search (<1s P99), out-of-the-box AI-powered insights, and flat ingestion-based pricing designed to retain 100% of traces affordably for debugging and optimizing production agents.


Premium Alternatives
Abliterated LLM provider for cyber tasks
Refuseless hosts GLM 5.3 Abliterated models through an OpenAI-compatible API for cybersecurity and coding work. The page states that prompts are not retained and shows integrations with OpenCode and Pi.
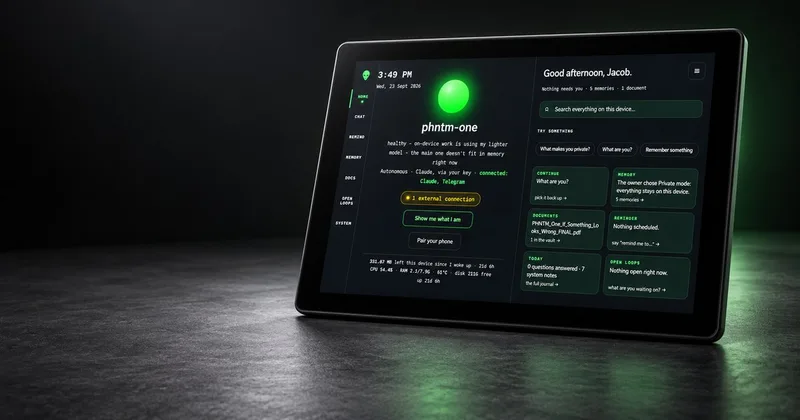
PHNTM ONE
PHNTM One is a private, local-first AI appliance: a hand-built desktop device (Raspberry Pi 5, 8 GB, 10.1″ touchscreen) that runs an on-device model (Gemma 3 4B) to provide a voice-capable assistant, memories, document reading, timers, Home Assistant integration and offline knowledge — sold as a one-time $549 purchase with no subscription and zero telemetry by default.
AletheionAGI
AletheionAGI provides a grounded-memory layer for AI systems that enforces evidence-bound delivery, namespace isolation, and policy authorization so AI readers cannot produce unsupported claims. It's targeted at production-facing use cases like customer support, commerce agents and internal copilots.

ClaudeThings
ClaudeThings provides a packaged, continuously-updating set of 89 specialized agents, 103 pre-built skills, and 181 slash commands that act as an AI engineering and marketing team for Claude Code — delivered as a private GitHub repo and installed with a single npx command. It adapts to any stack via a CLAUDE.md project manifest and is sold as a one-time purchase with lifetime updates.

Fireworks AI
Fireworks AI is an enterprise-grade platform for training, fine-tuning, and serving open and closed AI models, offering a drop-in replacement for closed-model APIs, an optimized inference engine, and tooling to own specialized intelligence and reduce AI spend.