
Prefactor
Prefactor is an agent observability and reliability platform that scores every AI agent run in real time (quality, drift and risk) and wires those evaluations into enforcement actions so failing or risky runs can be paused, blocked or routed for human approval before they act.
Prefactor is ai tools software teams evaluate for ai agents. Use this page to review pricing, integration signals, and the best alternatives before you commit.
Profile facts come from the vendor source. AiMatch labels unknown pricing or API details instead of estimating them.
Review official source →Quick Overview
Best for: AI Agents
What it does
AI Tools software for decision-makers comparing workflow fit and alternatives.
Best fit
AI Agents
Pricing snapshot
Free from Free for first 25,000 spans per month
Next step
Compare Prefactor with similar tools before you shortlist it.
Compare this tool before you shortlist it
Review alternatives, pricing posture, and workflow fit side by side.
Prefactor is a production-focused platform for agent observability, evaluation and enforcement. It captures every agent run as structured trace data (each LLM call, tool invocation and decision), scores runs with custom evals (including LLM-as-judge, technical and qualitative metrics), and wires those evaluations into actions so risky or failing runs can be paused, blocked or routed for human approval at runtime. The product is aimed at engineering and AI platform teams running agents in production and integrates via a CLI, TypeScript and Python SDKs, and native integrations for frameworks like LangChain and Claude.
The platform emphasizes a closed-loop reliability model: observe every run, evaluate with the evals you define, and act automatically or with human-in-the-loop enforcement. Prefactor also provides runtime visibility (traces & spans), custom spans to attach external context, versioning and environment promotion (dev → staging → prod) gated by evals, and enterprise security features such as least-privilege access, auditing, and sensitive-data detection.
Evaluate your AI Agents in real-time Discussion | Link
Own this listing?
Claim this page for a one-time $29 to add pricing, features, screenshots, verified owner details, and a clearly labeled 30-day category position after the profile is live.
Claim this listing for $29Key Features
Real-time evaluation
Scores every agent run in production the moment it happens for quality, drift and risk using configurable evals including LLM-as-judge, technical checks and qualitative metrics.
Closed-loop enforcement
Wires evaluations directly into action: hold, approve or block runs automatically or route high-risk actions to humans via the SDK or API so failures are caught live, not just charted.
SDKs & CLI
TypeScript and Python SDKs plus a CLI (prefactor init) that discovers agents across runtimes and instruments calls into streaming spans and live runs.
Native integrations
Native support for agent frameworks and platforms (LangChain, Claude, Vercel AI, OpenClaw, LiveKit) and connectors for coding and workflow tools.
Custom spans & grounding
Attach any datasource (GitHub, Linear, Jira, DBs, internal APIs) as custom spans to a run so evals can be grounded in external context and factual signals.
Versioning & lifecycle promotion
Immutable agent versioning (semver/commit/tag), schema management, dev/staging/prod environments and eval-gated promotion with instant rollback.
Sensitive-data detection & audit
Sensitive-data detection across categories, auditable records of decisions and scoped least-privilege access for enforcement actions.
Pricing
Free for your first 25,000 spans a month.
Free
Free for first 25,000 spans per month- First 25,000 spans free each month
- Drop-in SDK instrumentation and live scoring
Use Cases
Preventing harmful or risky agent actions
Pause or block high-risk actions (for example, PII leaks or destructive operations) at runtime and route them to human reviewers for approval before execution.
Continuous agent quality monitoring
Score agent outputs on real production traffic to detect drift and regressions using LLM-as-judge, technical checks and qualitative metrics, with metrics available per run and per agent version.
Agent development lifecycle and promotion
Version agents, validate them against production traffic, and promote only when evals pass to ensure newer agent versions improve performance and safety.
Grounded evaluations with external context
Attach data from GitHub, Jira, databases or internal APIs to runs so evaluations are grounded in the factual context of each decision.
Enterprise compliance and auditing
Provide auditable records, scoped access and sensitive-data detection to meet enterprise governance and security requirements.
Integrations
LangChain
Native SDK integration for instrumenting LangChain agents and capturing spans for every run.
Claude
Native integration to evaluate and enforce runs using Claude-based agents.
Vercel AI
Native integration for agents running on Vercel AI.
OpenClaw
Native integration for OpenClaw agent frameworks.
LiveKit
Native integration for LiveKit-powered agents.
Coding & workflow tools
Works with VS Code, GitHub Copilot, Cursor, n8n and other tools via native SDKs or OpenTelemetry spans.
Benefits
Limitations
Frequently Asked Questions
What is agent observability?
What is agent evaluation?
How do I instrument my agent with Prefactor?
What are custom spans, and how do they measure quality?
How does human-in-the-loop work?
How does Prefactor enforce at runtime?
Why do AI agents need identity and scoped access?
Getting Started
- 1 Step 1: Install the Prefactor CLI (prefactor init) to connect your workspace and discover agents.
- 2 Step 2: Add the TypeScript or Python SDK (native for LangChain, Claude, Vercel AI, OpenClaw & LiveKit) to instrument agent runs as spans.
- 3 Step 3: Define evals (LLM-as-judge, technical & qualitative metrics) and attach any custom spans or external context.
- 4 Step 4: Watch runs stream in live with traces, scores, latency and cost, then configure enforcement (block, hold, throttle, or route to humans).
- 5 Step 5: Use versioning and eval-gated promotion to move agents through dev → staging → prod and enable instant rollback when needed.
Support
docs
Documentation and SDK reference linked from the product site (Read the docs).
demo
Book a 30-minute walkthrough with an engineer (Book a demo).
community
Slack Community referenced on the site for community support and discussion.
self-serve
Get started — free (signup to the app) and CLI-based installation for self-serve onboarding.
API
https://prefactor.tech/
Compare Prefactor with similar tools
See how it stacks up against alternatives
Related Tools
View all 617 →
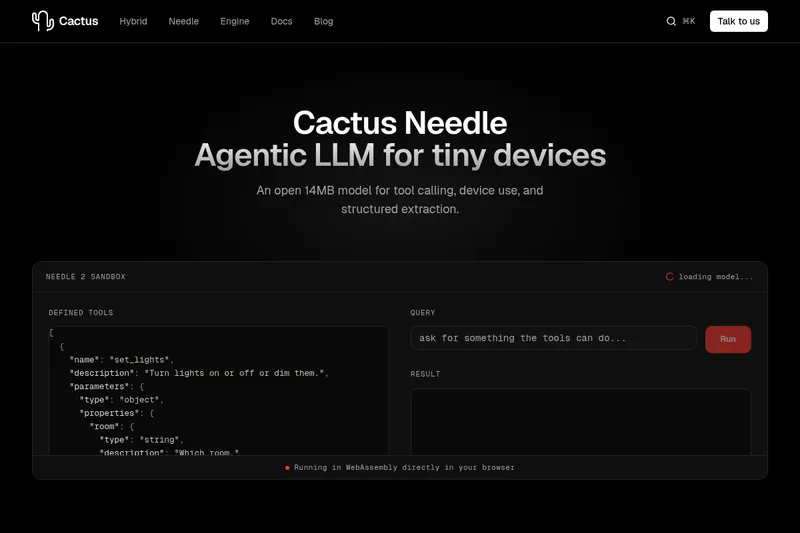
Needle2
Needle 2 is an open, production-ready 45M-parameter agentic LLM from Cactus designed for tool calling, device control, and structured extraction on extremely small devices; the shipped CQ2-bit binary is ~14 MB and runs in ~28 MB of RAM across Cortex-M, microcontrollers, phones, Raspberry Pi and WebAssembly.
The cheapest GPU cloud
Compute Cheap provides low-cost GPU compute for training and inference, offering H100 and H200 SXM GPUs as interruptible or reserved capacity with published per-GPU-hour pricing and a simple request/reserve/run workflow.
Oodle.ai
Oodle Agent Observability provides agent/LLM observability at scale with S3-backed columnar storage, fast search (<1s P99), out-of-the-box AI-powered insights, and flat ingestion-based pricing designed to retain 100% of traces affordably for debugging and optimizing production agents.


Premium Alternatives
Abliterated LLM provider for cyber tasks
Refuseless hosts GLM 5.3 Abliterated models through an OpenAI-compatible API for cybersecurity and coding work. The page states that prompts are not retained and shows integrations with OpenCode and Pi.
PHNTM ONE
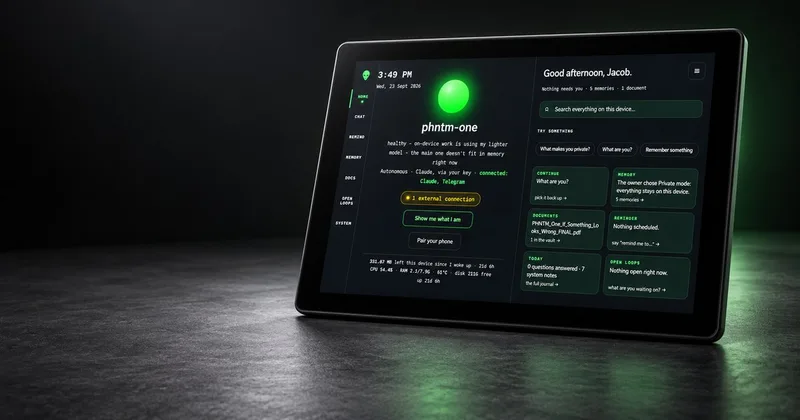
PHNTM One is a private, local-first AI appliance: a hand-built desktop device (Raspberry Pi 5, 8 GB, 10.1″ touchscreen) that runs an on-device model (Gemma 3 4B) to provide a voice-capable assistant, memories, document reading, timers, Home Assistant integration and offline knowledge — sold as a one-time $549 purchase with no subscription and zero telemetry by default.
AletheionAGI
AletheionAGI provides a grounded-memory layer for AI systems that enforces evidence-bound delivery, namespace isolation, and policy authorization so AI readers cannot produce unsupported claims. It's targeted at production-facing use cases like customer support, commerce agents and internal copilots.

ClaudeThings
ClaudeThings provides a packaged, continuously-updating set of 89 specialized agents, 103 pre-built skills, and 181 slash commands that act as an AI engineering and marketing team for Claude Code — delivered as a private GitHub repo and installed with a single npx command. It adapts to any stack via a CLAUDE.md project manifest and is sold as a one-time purchase with lifetime updates.