Redactle LLM Leaderboard
A public benchmark dashboard that evaluates how well large language models (LLMs) solve Redactle puzzles by running standardized evaluations and publishing ranked results, costs, and performance metrics.
Redactle LLM Leaderboard is research software teams evaluate for research. Use this page to review pricing, integration signals, and the best alternatives before you commit.
Profile facts come from the vendor source. AiMatch labels unknown pricing or API details instead of estimating them.
Review official source →Quick Overview
Best for: Research
What it does
Research software for decision-makers comparing workflow fit and alternatives.
Best fit
Research
Pricing snapshot
Contact for pricing
Next step
Compare Redactle LLM Leaderboard with similar tools before you shortlist it.
Compare this tool before you shortlist it
Review alternatives, pricing posture, and workflow fit side by side.
The Redactle LLM Leaderboard is a public dashboard on redactle.net that measures how different language models perform at solving Redactle puzzles (redacted Wikipedia articles). The page runs standardized evaluations under multiple configurations (for example: 500 words no-hint, 100 words with 3 hints, and a cheating-enabled setting that can query Wikipedia’s API) and reports per-model metrics such as solve rate, score, cost per run, and runtime. The leaderboard is intended for comparing model capability, cost, and speed under the same puzzle-solving rules; it also links to evaluation code to aid reproducibility and further analysis.
The page deliberately omits article titles and per-article excerpts to avoid spoiling puzzles; instead it publishes aggregated results, method notes, and trade-off visualizations so readers can understand relative model performance without revealing puzzle content.
A compact comparison of how language models solve Redactle under distinct evaluation configurations.
Own this listing?
Claim this page for a one-time $29 to add pricing, features, screenshots, verified owner details, and a clearly labeled 30-day category position after the profile is live.
Claim this listing for $29Key Features
Standardized multi-configuration evaluations
Runs models under several fixed configurations (e.g., 500 words no-hint, 100 words with up to 3 hints, 100 words with research allowed) and reports results per configuration.
Per-model metrics and ranking
Displays solve counts, attempts, solve rate, score, cost per run and run time for many LLM configurations (examples include Gemini, Grok, GPT-5.6, GLM, Claude Sonnet).
Method notes and scoring rules
Explains how scores are computed (accepted guesses above title word-count par, hint penalties, attempt cutoffs like 30 accepted guesses in the 500-word evaluation).
Trade-off visualizations
Includes cost-versus-score and speed-versus-score visualizations and a quadrant view showing better/worse trade-offs across models.
Reproducible evaluation code
Links to evaluation code on GitHub for inspection and reproducibility.
Published result snapshots
Published leaderboard snapshots with aggregate counts and a recent publication date (e.g., Sep 2, 2026).
Pricing
Current pricing details are not available from the vendor source.
Use Cases
Benchmarking LLMs
Compare model accuracy, cost, and latency on a focused task (solving redacted encyclopedia articles) under consistent rules.
Model selection and cost analysis
Choose models or configurations that balance solve rate, runtime, and monetary cost per run for similar generative tasks.
Research and reproducibility
Use the linked evaluation code and method notes to reproduce runs or adapt the benchmark for further experiments.
Curiosity and public reporting
Provide players and the public with an entertaining, empirical view of current LLM capabilities on a puzzle task.
Integrations
GitHub (evaluation code)
Evaluation code is available on GitHub for inspection and reproduction of runs.
Wikipedia API (optional in cheating configuration)
A 'cheating allowed' evaluation configuration lets models research through Wikipedia’s API as part of the test.
Benefits
Limitations
Frequently Asked Questions
No verified FAQs are available.
Getting Started
- 1 Visit the LLM leaderboard page on redactle.net/llm-leaderboard to view published results and news.
- 2 Read the method notes (scoring rules and configuration descriptions) on the page to understand how evaluations were run.
- 3 Follow the link to the evaluation code on GitHub to inspect or reproduce the benchmark.
- 4 Compare models by configuration, cost, and runtime; consult the trade-off visualizations to select candidates for further testing.
Support
docs
Method notes, scoring rules, and trade-off explanations available on the LLM leaderboard page.
github
Evaluation code linked from the leaderboard page for issues, reproduction, and contributions.
support link / donations
Support, Ko-fi donations and an in-site Support link are mentioned for feedback and ad-free access for supporters.
discord
Contact via Discord for feedback (the page invites contacting the author on Discord).
API
Compare Redactle LLM Leaderboard with similar tools
See how it stacks up against alternatives
Related Tools
View all 143 →
ThoughtDAG
ThoughtDAG is an open-source, desktop-first application that makes LLM context visible, editable, and reproducible by representing context as an editable directed acyclic graph (wires = context) and letting users preview and control exactly what the model receives.
LLM Attention Visualization
A browser-based interactive visualization that shows how transformer LLMs allocate attention to past tokens during generation by aggregating attention weights and value magnitudes across heads and layers.
PilotCite
PilotCite is a SaaS platform that helps brands monitor and improve their visibility in AI-generated answers (ChatGPT, Perplexity, Google AI, Gemini, Claude, Copilot, Grok) by tracking citations, auditing site citability, benchmarking competitors, and generating source-backed content.

Knowledge graph skill for Claude/Kimi Code
SysEdge is an ontological knowledge graph and CLI for multi-agent Claude Code and Kimi Code teams that models requirements, tests, and architecture standards to surface specification, test, and standards gaps before code ships and to reduce agent orientation tokens.
HieraticBench
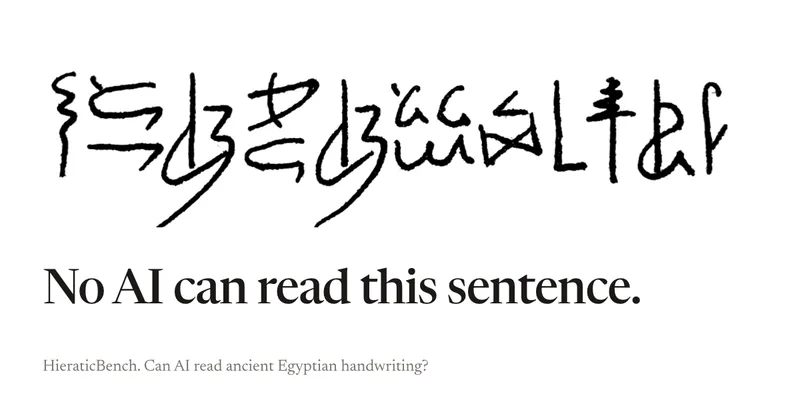
HieraticBench is an open benchmark for testing whether AI models can identify and read hieratic, the cursive handwriting of ancient Egypt. It includes a public leaderboard, evaluation harness, and dataset of documents and individual signs.

CiteRank
CiteRank is a weekly SaaS monitoring tool that re-asks buyer questions of major AI answer engines (ChatGPT, Perplexity, Google AI Overviews, Gemini and Claude) to record whether they cite your site, name your brand, or leave you absent, and delivers board-style reports and competitor/source lists.
Premium Alternatives
CiteRank
CiteRank is a weekly SaaS monitoring tool that re-asks buyer questions of major AI answer engines (ChatGPT, Perplexity, Google AI Overviews, Gemini and Claude) to record whether they cite your site, name your brand, or leave you absent, and delivers board-style reports and competitor/source lists.
OutlierKit
OutlierKit is a YouTube competitor analysis and outlier research platform that maps niche-wide opportunities from a single seed channel, surfaces overperforming videos, analyzes audience psychology, sponsors, and monetization, and offers AI-powered script/hook analysis and integrations for creators, teams, and agencies.
AI ChatDocs
AI ChatDocs is a GPT-4 powered document chat and summarization tool that lets users upload PDFs, Word/PPT/Docx/TXT files, websites, sitemaps and YouTube videos to generate summaries, extract references, and interactively chat with document content.
SermonAI
SermonAI is a web-based sermon preparation platform for pastors, combining AI-assisted research and writing with planning, sermon organization, preaching tools, and content repurposing. Its AI research can be tailored to a pastor’s denomination, Bible translation, and trusted voices.