Agent Memory Leaderboard
Agent Memory Leaderboard is an open public benchmark and evaluation platform for comparing agent memory systems (textual and coding) under a unified Add/Search evaluation flow, offering public leaderboards, an API contract, and tooling for academic and commercial submissions.
Agent Memory Leaderboard is ai agents software teams evaluate for education & research. Use this page to review pricing, integration signals, and the best alternatives before you commit.
Profile facts come from the vendor source. AiMatch labels unknown pricing or API details instead of estimating them.
Review official source →Quick Overview
Best for: Education & Research
What it does
AI Agents software for decision-makers comparing workflow fit and alternatives.
Best fit
Education & Research
Pricing snapshot
Free from Free
Next step
Compare Agent Memory Leaderboard with similar tools before you shortlist it.
Compare this tool before you shortlist it
Review alternatives, pricing posture, and workflow fit side by side.
Agent Memory Leaderboard
Agent Memory Leaderboard is a public benchmark space for evaluating and ranking agent memory systems focused on textual and coding memory. It uses a unified end-to-end flow where participants provide Add and Search endpoints (or code for platform deployment) while the platform runs Answer, Eval, auditing, and public leaderboard publication. The platform locks the answering model, prompts, scoring rules, dataset bundles, Top K and aggregation to make leaderboard scores reflect the memory subsystem itself. The offering is aimed at researchers, open-source maintainers and commercial product teams and supports both hosted API and code-submission evaluation routes.
面向开发者、研究团队与商业公司的智能体长期记忆系统公开评测。统一 Add / Search 协议,由平台统一执行 Answer 与 Eval。
Own this listing?
Claim this page for a one-time $29 to add pricing, features, screenshots, verified owner details, and a clearly labeled 30-day category position after the profile is live.
Claim this listing for $29Key Features
Public Leaderboard
Public ranking pages separated by track (Textual, Coding, Multimodal) with filterable tables, metric breakdowns, and public submission records.
Unified Add/Search Evaluation Flow
A standardized synchronous Add and Search API contract that participants must implement; the platform calls Add by sample and Search per question and preserves the response order and Top K semantics.
Evaluation Modes (smoke & full)
Separate compatibility smoke endpoint for integration checks (private) and a full formal evaluation mode (queued, audited, and eligible for public leaderboard).
Multiple Participation Routes
Support for hosted API submissions (participants host Add/Search and receive an Eval Key) and code submissions (public GitHub + Docker for platform deployment).
Detailed API Contract & Error Handling
A fixed Add/Search schema, success semantics (synchronous HTTP 200 with success=true), Top K limits, health checks, authentication schemes, and bounded retry/error behaviors.
Reproducibility & Auditability
Platform retains request/response evidence, timing, errors, and dataset/pipeline hashes for review; submissions must disclose original work and changes for repro and review.
Participation & Rewards Program
First-cycle challenge with deadlines, reward tiers for academic entries (ChatGPT Pro/Plus months) and a community contribution plan (Kimi Token), plus public/academic/commercial boards.
Pricing
Participation in the evaluation/challenge is free; participants are responsible for their own hosting costs.
Free Participation
Free- Submission to the challenge is free of charge
- Participants cover their own API, database, bandwidth, and compute costs; the platform covers Answer/Eval orchestration
Use Cases
Academic method benchmarking
Researchers submit open GitHub repositories or hosted APIs to evaluate memory architectures on textual or coding benchmarks and appear on the Academic Methods board.
Commercial product evaluation
Product teams submit stable product API versions (without opening source) to be evaluated and ranked on the Commercial Products board.
Regression and integration testing
Teams can run private smoke tests and repeated eval runs to verify Add/Search compatibility and ensure stable behavior before public submission.
Reproducible comparison of memory systems
Compare different Add/Search implementations under a locked answering/scoring pipeline to isolate memory subsystem capabilities.
Integrations
Add/Search API
Synchronous HTTP(S) Add and Search endpoints (Token, Bearer, or X-Api-Key auth) that the platform calls for ingestion and retrieval.
GitHub / Docker
Code-submission integration where participants provide a public GitHub repo and Docker startup command for platform deployment and evaluation.
Platform Answer/Eval pipeline
Participant systems integrate with the platform's answer-generation and scoring pipelines via the declared contract to produce reproducible results.
Benefits
Limitations
Frequently Asked Questions
Is participation paid or free?
What is the difference between an Eval Key and a Memory System Key?
What counts as a valid submission?
Getting Started
- 1 Step 1: Choose an evaluation route — hosted Add/Search API (receive Eval Key) or code submission (public GitHub + Docker).
- 2 Step 2: Implement the synchronous Add/Search contract and verify endpoint reachability and health as described in the API Guide.
- 3 Step 3: Run a smoke test using the issued Eval Key to validate synchronous Add → Search → Answer → Evaluate flow, then submit a full evaluation when ready.
Support
Participation and evaluation questions can be sent to [email protected].
docs
User Documentation and API Guide available on the Agent Memory Leaderboard site (see the Evaluation / API Guide pages).
social
Official channels include an official WeChat account and X/Twitter handle @AgentMemoryL for releases and announcements.
API
API Guide and user documentation available from the Agent Memory Leaderboard site (see the Evaluation / API Guide pages).
Standard quotas: smoke mode roughly 1 per hour; full mode roughly 1 every 3 months; platform-specified concurrency and Top K limits apply (Top K = 100 for formal evaluations).
Compare Agent Memory Leaderboard with similar tools
See how it stacks up against alternatives
Related Tools
View all 560 →
Needle2
Needle 2 is an open, production-ready 45M-parameter agentic LLM from Cactus designed for tool calling, device control, and structured extraction on extremely small devices; the shipped CQ2-bit binary is ~14 MB and runs in ~28 MB of RAM across Cortex-M, microcontrollers, phones, Raspberry Pi and WebAssembly.
The cheapest GPU cloud
Compute Cheap provides low-cost GPU compute for training and inference, offering H100 and H200 SXM GPUs as interruptible or reserved capacity with published per-GPU-hour pricing and a simple request/reserve/run workflow.
Oodle.ai
Oodle Agent Observability provides agent/LLM observability at scale with S3-backed columnar storage, fast search (<1s P99), out-of-the-box AI-powered insights, and flat ingestion-based pricing designed to retain 100% of traces affordably for debugging and optimizing production agents.


AgentDrive
AgentDrive is a cloud filesystem by Token Canopy that provides durable, shared drives for AI agents and human teammates to store and share files and context across work sessions, with an API intended for direct agent use.
Nous
Nous is an open-source context graph for agentic GTM (go-to-market) teams that centralizes identity-resolved people and company data from multiple GTM tools so agents can read a single, source-traced account context in one call. It is available as a hosted service and as a self-hostable stack.
Premium Alternatives
PHNTM ONE
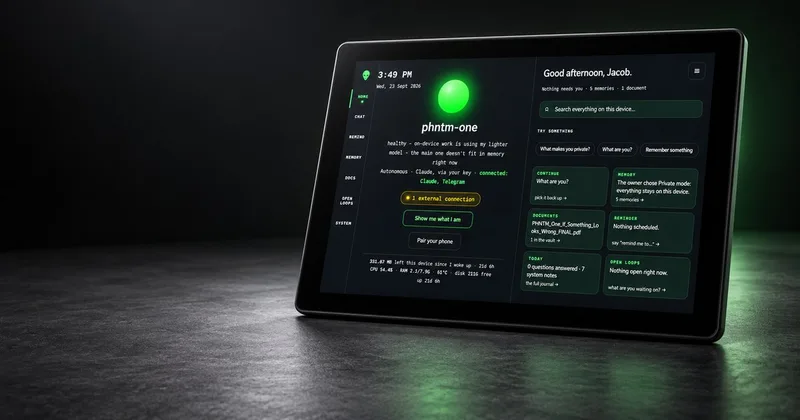
PHNTM One is a private, local-first AI appliance: a hand-built desktop device (Raspberry Pi 5, 8 GB, 10.1″ touchscreen) that runs an on-device model (Gemma 3 4B) to provide a voice-capable assistant, memories, document reading, timers, Home Assistant integration and offline knowledge — sold as a one-time $549 purchase with no subscription and zero telemetry by default.
AletheionAGI
AletheionAGI provides a grounded-memory layer for AI systems that enforces evidence-bound delivery, namespace isolation, and policy authorization so AI readers cannot produce unsupported claims. It's targeted at production-facing use cases like customer support, commerce agents and internal copilots.

ClaudeThings
ClaudeThings provides a packaged, continuously-updating set of 89 specialized agents, 103 pre-built skills, and 181 slash commands that act as an AI engineering and marketing team for Claude Code — delivered as a private GitHub repo and installed with a single npx command. It adapts to any stack via a CLAUDE.md project manifest and is sold as a one-time purchase with lifetime updates.
Miro
Miro is a collaborative visual workspace and AI platform that integrates intelligent agents (Sidekicks), visual multi-step workflows (Flows), and connectors to bring team context and external data into a shared canvas to accelerate planning, design, and decision-making across organizations.
Sitemanagerai
Site Manager AI is a web + iOS app that provides UK construction site managers and foremen instant, regulation-aware answers, on-site photo hazard analysis, and fast drafting of risk assessments, method statements and site reports.